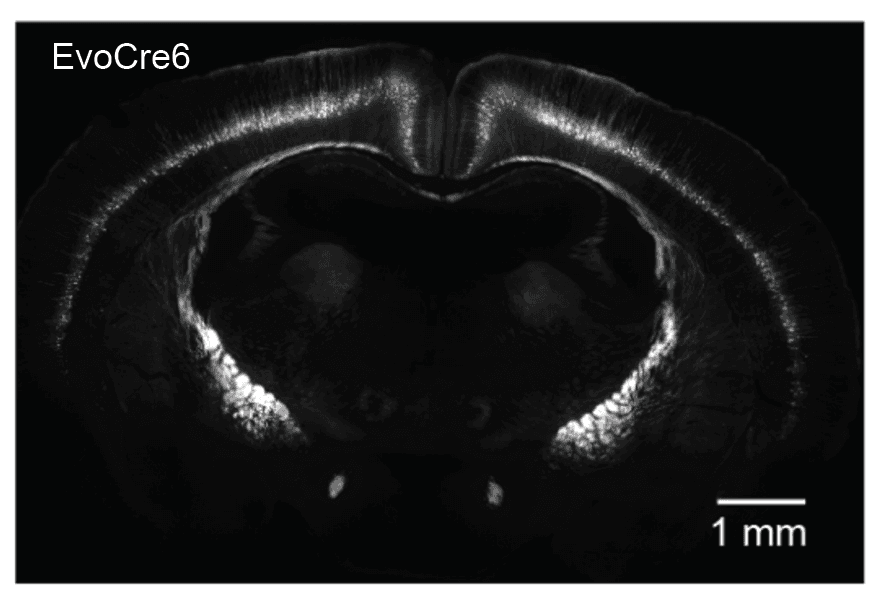
We reveal that Evo 2 is capable of designing–from scratch–enhancers, or cis-regulatory elements, that successfully target specific neuronal populations in the living mouse brain. Then we extend these findings to novel proteins, protein-RNA systems like CRISPR-Cas9 loci, epitope-specific antibodies, and whole bacteriophage genomes in silico.
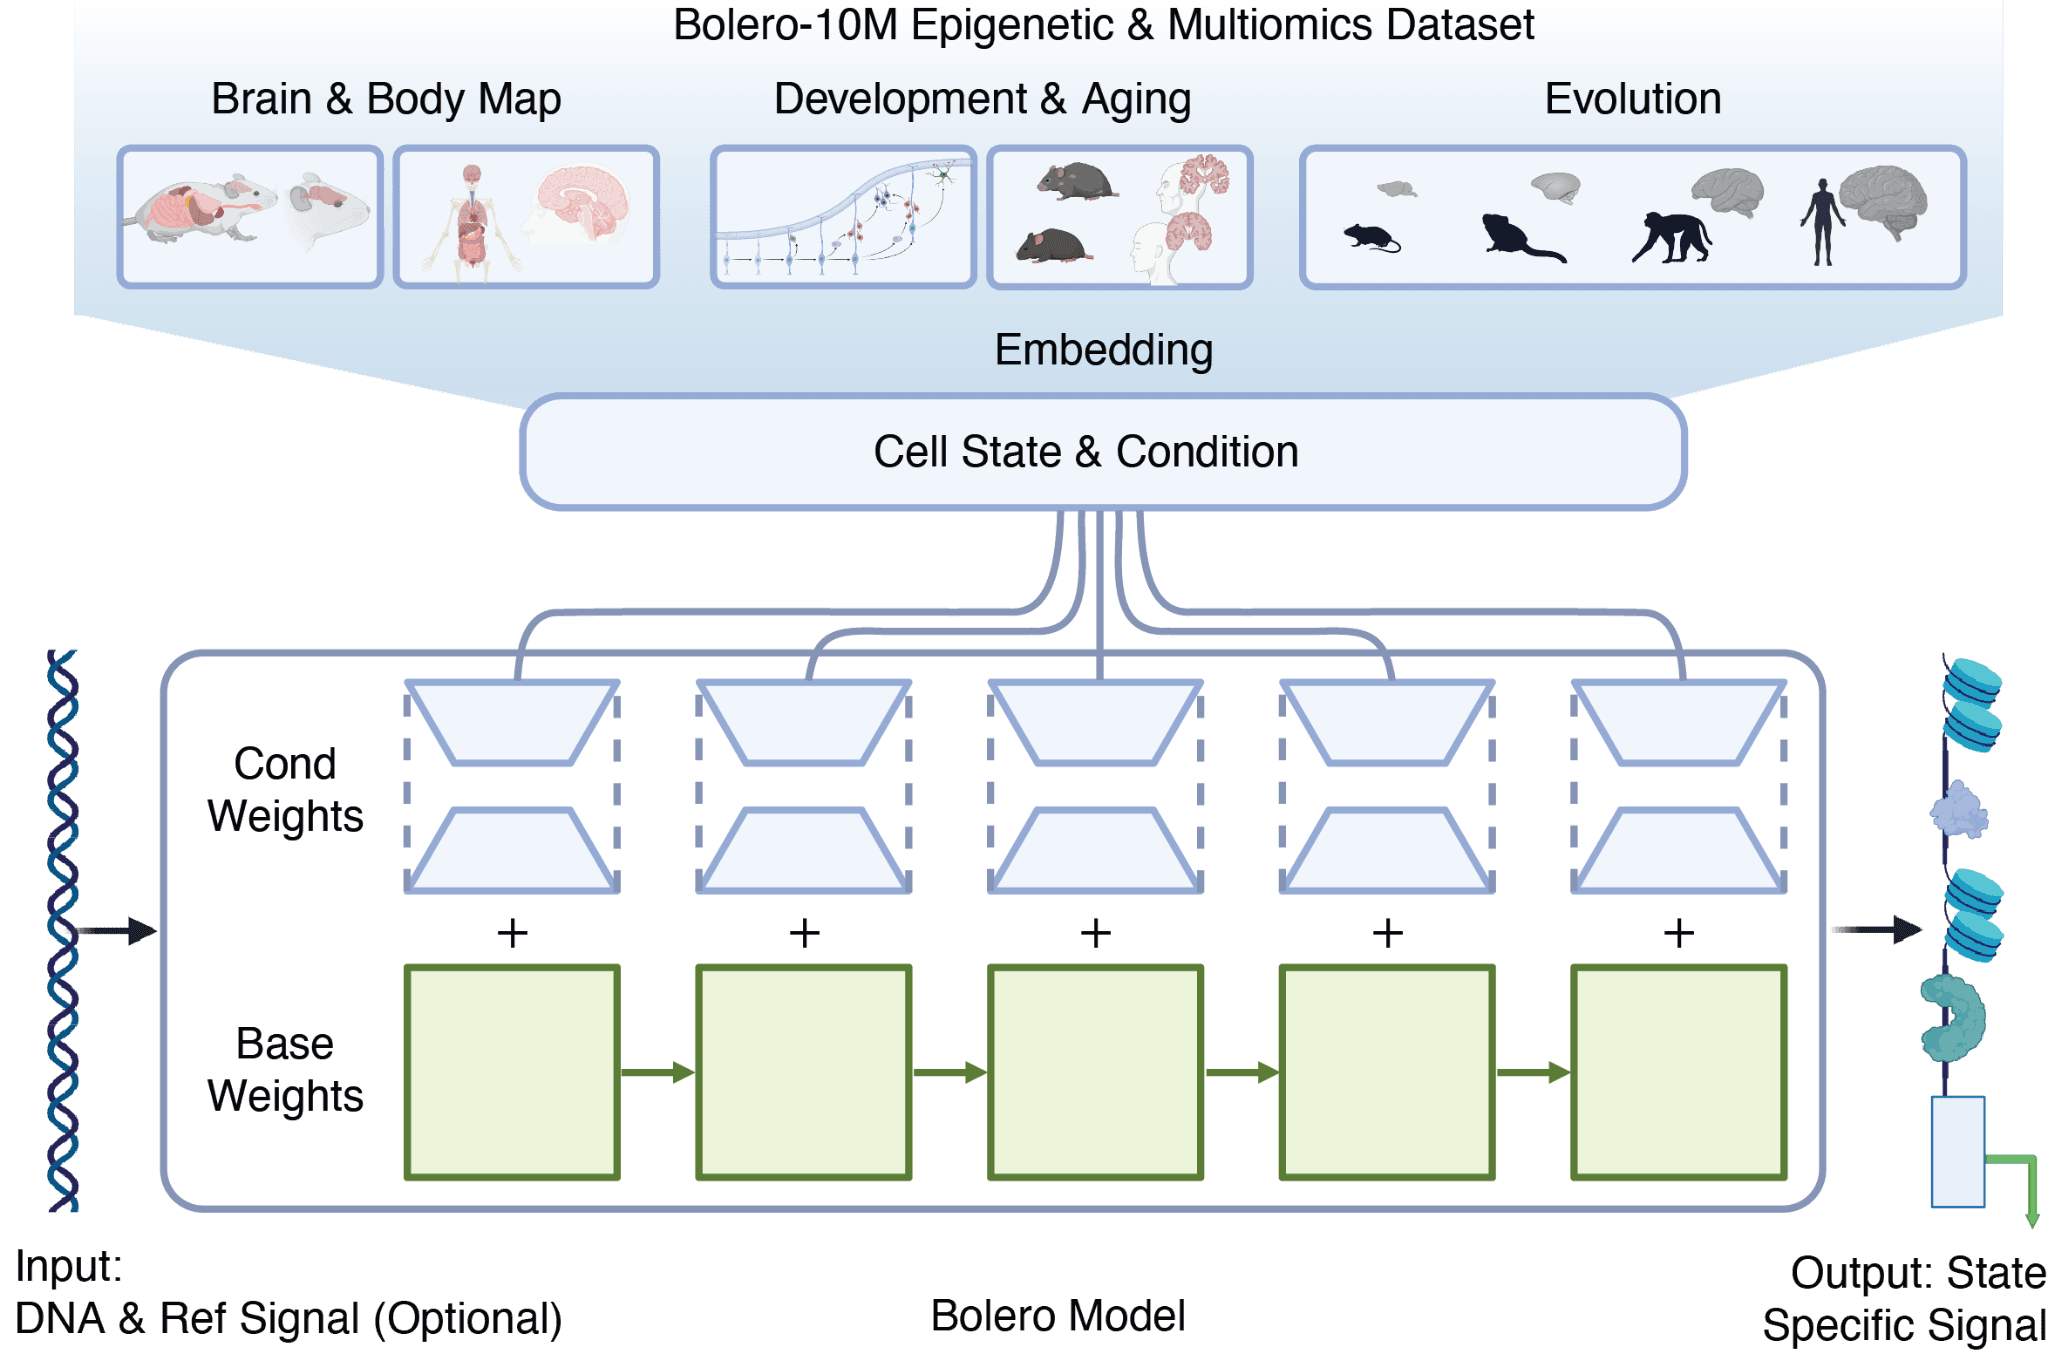
If cell state is a song, our DNA is the sheet music, but the epigenome is the orchestra. DNA provides the same basic sequence, but how different cell types use that sequence depends on which transcription factors are present and the level of chromatin accessibility. Have you ever heard Ravel’s Boléro? In that piece, each instrument riffs off the same musical theme to create variety in a massive musical crescendo. The intricate processes modifying gene expression are akin to this, and Ravel’s playful orchestral experiment is the namesake for our new cell-state predictive model, Bolero, posted today on bioRxiv.
One of the goals of the Virtual Cell Challenge is to build a community of people who see the possibilities of applying machine learning to complex biology.
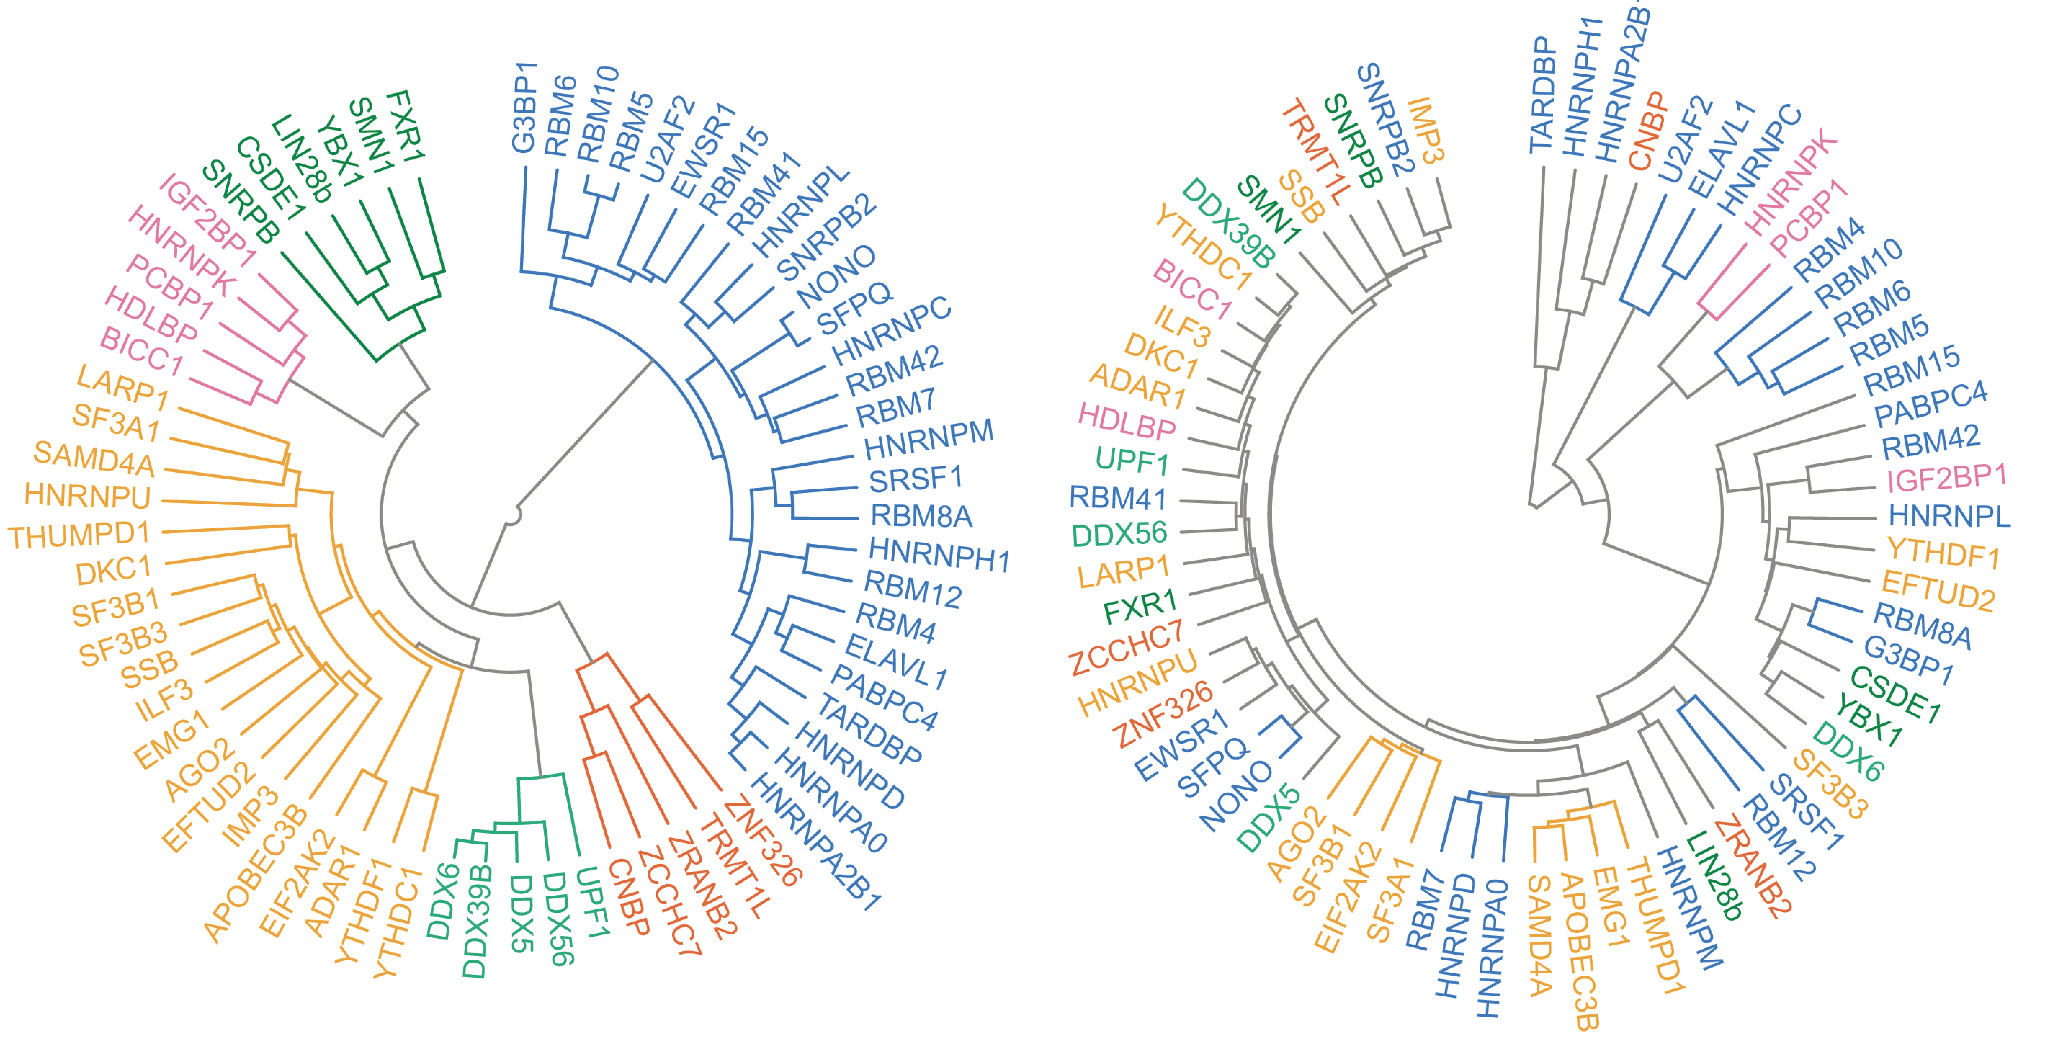
RNA-binding proteins (RBPs) guide nearly every step of an RNA molecule's life. From the moment a gene is transcribed, they help determine how the transcript is spliced, where it travels in the cell, how often it is translated into protein, and when it is broken down. Humans have roughly 1,500 RBPs, accounting for about 7.5% of our protein-coding genes, and their malfunction has been linked to a range of diseases, including cancer.
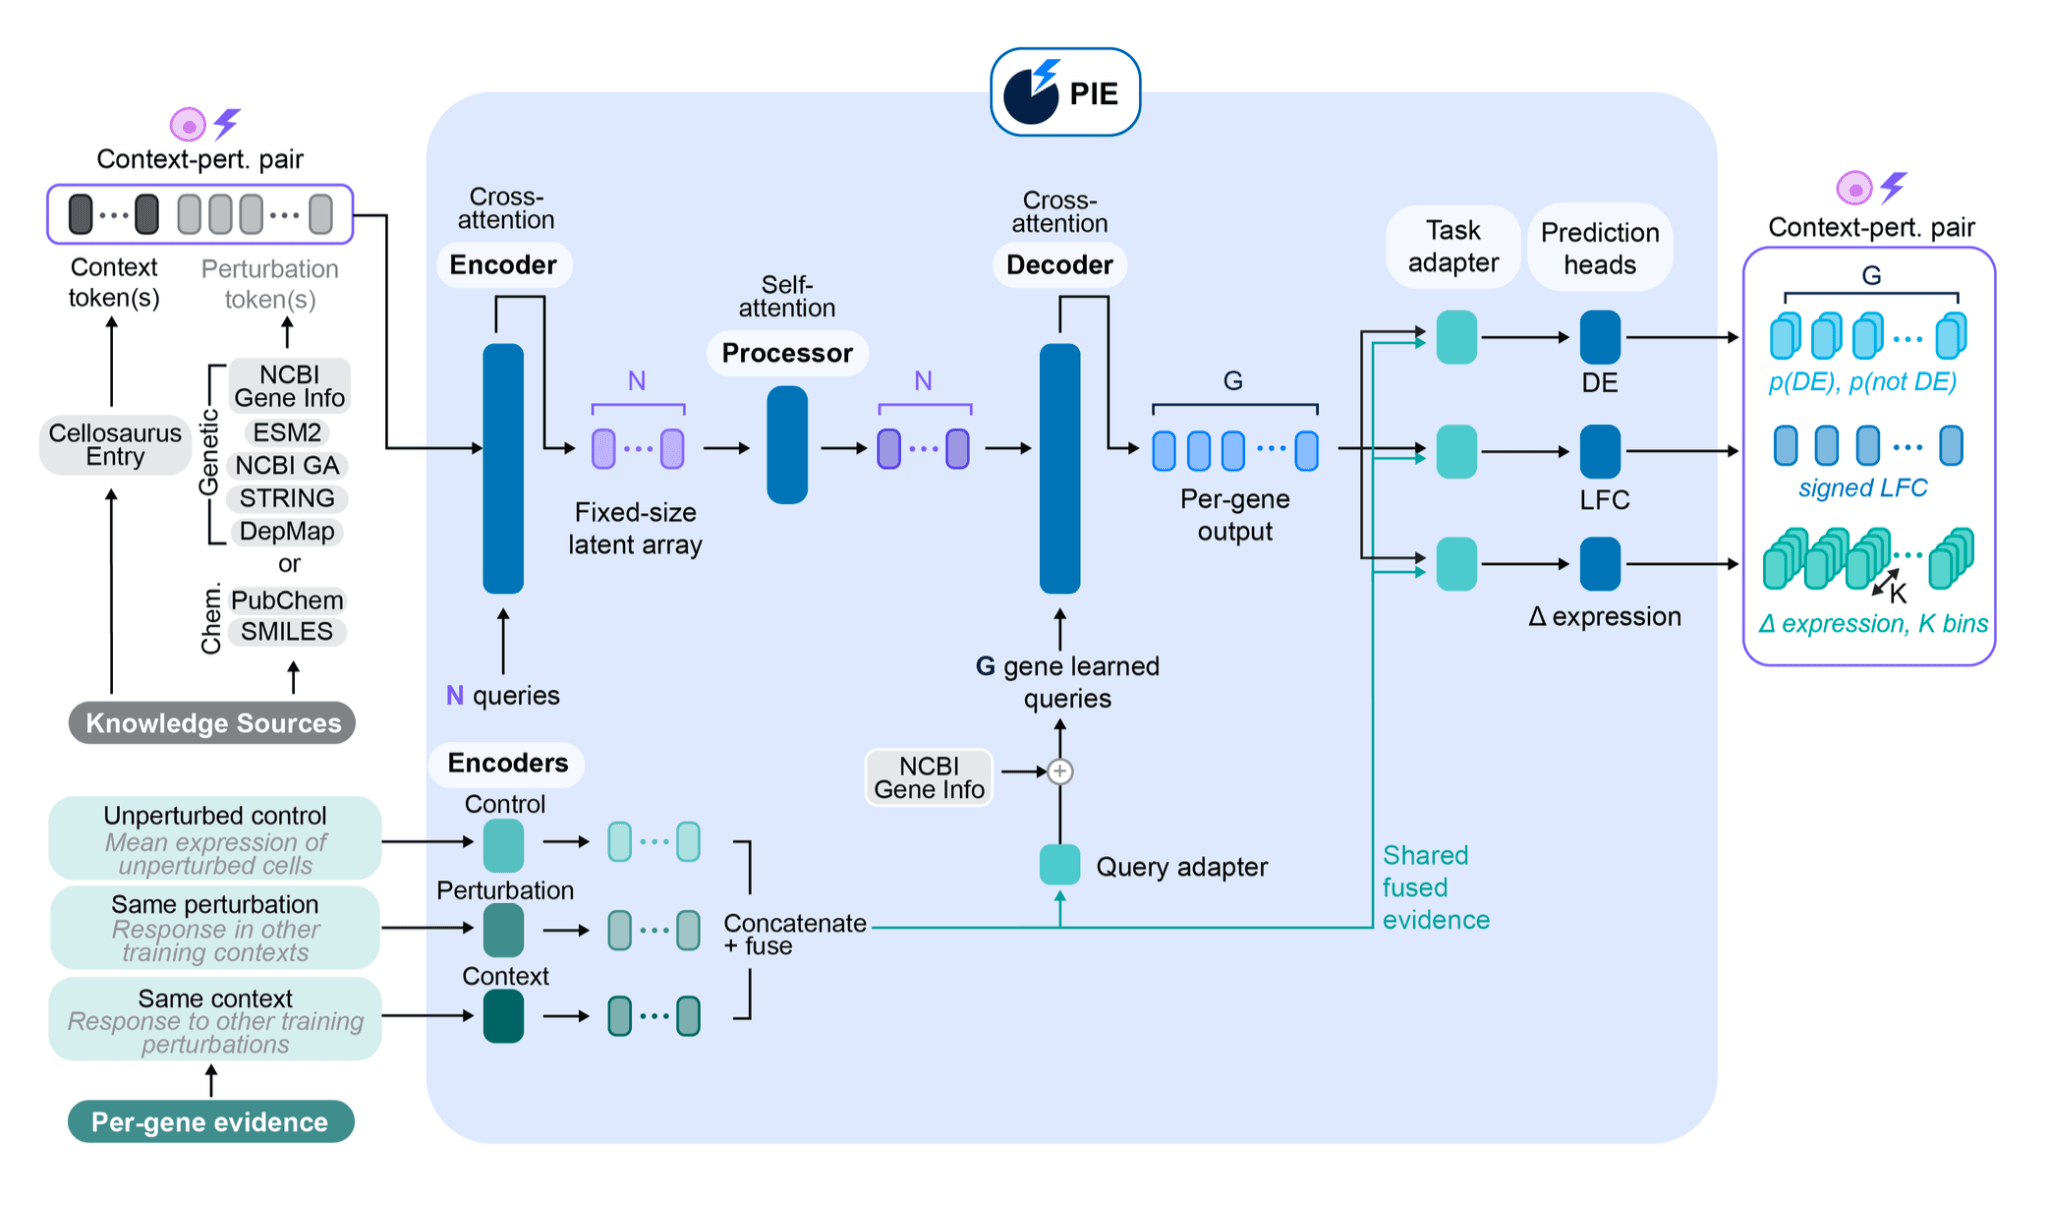
PIE is a zero-shot perturbation-effect model that predicts population-level transcriptomic responses, including which genes are differentially expressed, their direction of change, and its magnitude. Rather than learning only from perturbation experiments, PIE conditions on human-curated knowledge sources such as Cellosaurus cell line records, NCBI Gene entries, Gene Ontology annotations, DepMap dependency profiles, and PubChem compound entries. A Perceiver IO-inspired architecture handles sparse, variable sets of these sources, and each gene is represented by its natural-language description, so PIE adapts to different gene vocabularies across studies and can predict outcomes for genes not seen during training. PIE predicts responses for unseen context-perturbation combinations in a single forward pass without fine-tuning, identifying differentially expressed genes with up to 3.2x the AUPRC of the strongest baseline.